Ne için kullanılır, nasıl uyarlanır ve değişkenler ne anlama gelir.
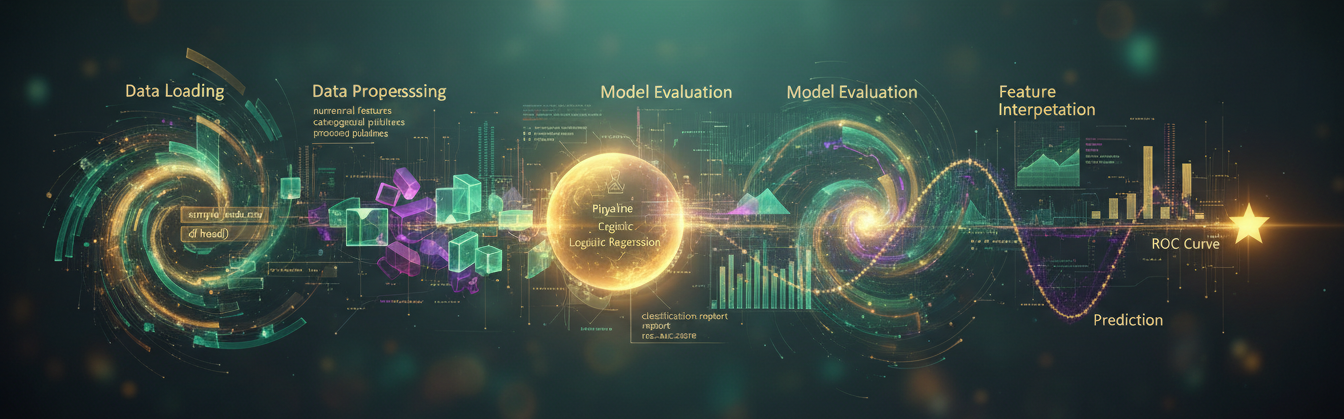
Tahmine dayalı müşteri puanlama (Predictive Lead Scoring) modeli geliştirmek için kapsamlı bir kod yapısı oluşturur. Veri yükleme, ön işleme, özellik mühendisliği, model eğitimi ve değerlendirme adımlarını içeren eksiksiz bir iş akışı sunar.
Makine öğrenmesi tabanlı müşteri puanlama sistemleri, satış ekiplerinin en değerli potansiyel müşterilere odaklanmasını sağlar. Bu prompt, veri bilimi projelerinde standart olarak kullanılan adımları takip ederek, eksik veri yönetimi, kategorik kodlama, özellik ölçeklendirme ve yeni özellik türetme gibi kritik ön işleme tekniklerini içerir.
Model eğitimi aşamasında, belirtilen model türü kullanılarak eğitim ve test setlerine ayrılmış veri üzerinde çalışır. Değerlendirme aşamasında ise sınıflandırma problemleri için standart metrikler (doğruluk, kesinlik, duyarlılık, F1 skoru, AUC-ROC) hesaplanır ve karmaşıklık matrisi görselleştirilir. Kod yapısı, profesyonel veri bilimi projelerinde kullanılabilecek şekilde modüler ve yorumlanabilir olarak tasarlanmıştır.
{ }Değişken Açıklamaları:
[PROGRAMMING LANGUAGE]: Kodun yazılacağı programlama dili. Örneğin: Python, R, Julia
Generate a comprehensive code structure for a Predictive Lead Scoring model. The code should be in [PROGRAMMING LANGUAGE] and utilize the following [LIBRARIES].
**Step 1: Data Loading and Initial Exploration**
Provide code to load a sample dataset (assume CSV) and display its first 5 rows, along with basic descriptive statistics and data types. Comment on potential missing values or inconsistencies based on [DATASET COLUMNS].
**Step 2: Data Preprocessing and Feature Engineering**
Generate code for common preprocessing steps, including:
- Handling missing values (e.g., imputation for numerical, mode for categorical).
- Encoding categorical features (e.g., One-Hot Encoding).
- Scaling numerical features (e.g., StandardScaler).
- Create at least two relevant new features based on common lead scoring practices (e.g., interaction terms, recency features, or frequency features if applicable to [DATASET COLUMNS]).
**Step 3: Model Definition and Training**
Write code to define and train a [MODEL TYPE] model. Ensure the dataset is split into training and testing sets (e.g., 80/20 split). Clearly define features (X) and the target variable (y), which is [TARGET VARIABLE].
**Step 4: Model Evaluation**
Provide code to evaluate the trained model on the test set. Include metrics relevant for classification problems, such as accuracy, precision, recall, F1-score, and AUC-ROC. Display a classification report and a confusion matrix.
**Step 5: Predictive Scoring and Interpretation**
Generate code to use the trained model to predict lead scores (probabilities) for new, unseen data. Show how to interpret these scores (e.g., assigning a 'High', 'Medium', 'Low' lead category based on probability thresholds). Provide a basic example of how to make a single prediction.
Generate a comprehensive code structure for a Predictive Lead Scoring model. The code should be in [PROGRAMMING LANGUAGE] and utilize the following [LIBRARIES].
**Step 1: Data Loading and Initial Exploration**
Provide code to load a sample dataset (assume CSV) and display its first 5 rows, along with basic descriptive statistics and data types. Comment on potential missing values or inconsistencies based on [DATASET COLUMNS].
**Step 2: Data Preprocessing and Feature Engineering**
Generate code for common preprocessing steps, including:
- Handling missing values (e.g., imputation for numerical, mode for categorical).
- Encoding categorical features (e.g., One-Hot Encoding).
- Scaling numerical features (e.g., StandardScaler).
- Create at least two relevant new features based on common lead scoring practices (e.g., interaction terms, recency features, or frequency features if applicable to [DATASET COLUMNS]).
**Step 3: Model Definition and Training**
Write code to define and train a [MODEL TYPE] model. Ensure the dataset is split into training and testing sets (e.g., 80/20 split). Clearly define features (X) and the target variable (y), which is [TARGET VARIABLE].
**Step 4: Model Evaluation**
Provide code to evaluate the trained model on the test set. Include metrics relevant for classification problems, such as accuracy, precision, recall, F1-score, and AUC-ROC. Display a classification report and a confusion matrix.
**Step 5: Predictive Scoring and Interpretation**
Generate code to use the trained model to predict lead scores (probabilities) for new, unseen data. Show how to interpret these scores (e.g., assigning a 'High', 'Medium', 'Low' lead category based on probability thresholds). Provide a basic example of how to make a single prediction.
Bu Prompt Seni Bekliyor
Tabnine için hazırlanmış bu promptu anında kopyala, kullan.
Tek dosyalı, standart paylaşımlı hosting ortamında çalışabilen profesyonel kurumsal web sitesi oluşturmanızı sağlar.Hero bölümü, hakkında, hizmetler, ...
Yazılım projelerinde kod kalitesi, mimari yapı veya belirli bir teknik sorun hakkında sistematik ve uygulanabilir öneriler almak, sürdürülebilir geliş...
"Tebrikler! Bu prompt, detaylı ve kapsamlı bir Tahmine Dayalı Müşteri Puanlama Kodu iskeleti sunuyor. Başlık anlamlı ve prompt'un amacını açıkça ifade ediyor. Konu-araç uyumu da mükemmel, çünkü Tabnine'ın kod tamamlama yetenekleri ile makine öğrenimi projesinin her aşamasına yönelik örnek kodlar sağlanıyor.
Prompt, veri yükleme, ön işleme, özellik mühendisliği, model eğitimi, değerlendirme ve tahmin etme gibi tüm kritik adımları kapsamlı bir şekilde ele alıyor. Değişken tanımları da oldukça açık ve kullanışlı. Ayrıca, kod bloklarının içeriği ve yorumlamaları çok detaylı ve açıklayıcı.
Genel olarak, bu prompt mükemmel bir başlangıç noktası sağlıyor ve Tabnine kullanarak hızlı bir şekilde uyarlanabilir, özelleştirilmiş bir makine öğrenimi projesi oluşturmanıza yardımcı olacak. Tebrikler, bu prompt gerçekten benzersiz ve eksiksiz!"
Yeni içeriklerden haberdar olun
Prompt, blog, rehber ve forumda yeni yayınlar için tarayıcı bildirimi alın.
Çerez Bildirimi
Zorunlu çerezler her zaman çalışır. Kabul edersen istatistik (Google Analytics) ve kişiselleştirilmiş reklam çerezleri de kullanılır; reddedersen kullanılmaz.
Detaylı bilgi
Bu özellik üyelere özel
Ücretsiz üye ol ya da giriş yap; giriş yaptıktan sonra bu sayfaya geri dönersin.